Create with MOSS, share your experiments, and meet people exploring what these models can do. Artwork, tutorials, workflows, tools and content introducing MOSS research and releases are all welcome.
<aside> ↗
👾Join the Creator Partner Program on Discord
</aside>
<aside>
Join the MOSS Discord to take part. Tell us what you like to make.
Pick a model for your project, use an API, or run it locally. Any content about MOSS is welcome.
MOSS builds multimodal models for understanding and creating across images, speech, sound and video. CPP brings creators closer to the models and the people behind them. Whether you make finished artwork, publish experiments, teach a workflow or build tools for other creators, there is room for your approach.
Your work. Your way of making it. Meet MOSS ↗
Put your idea in the frame.
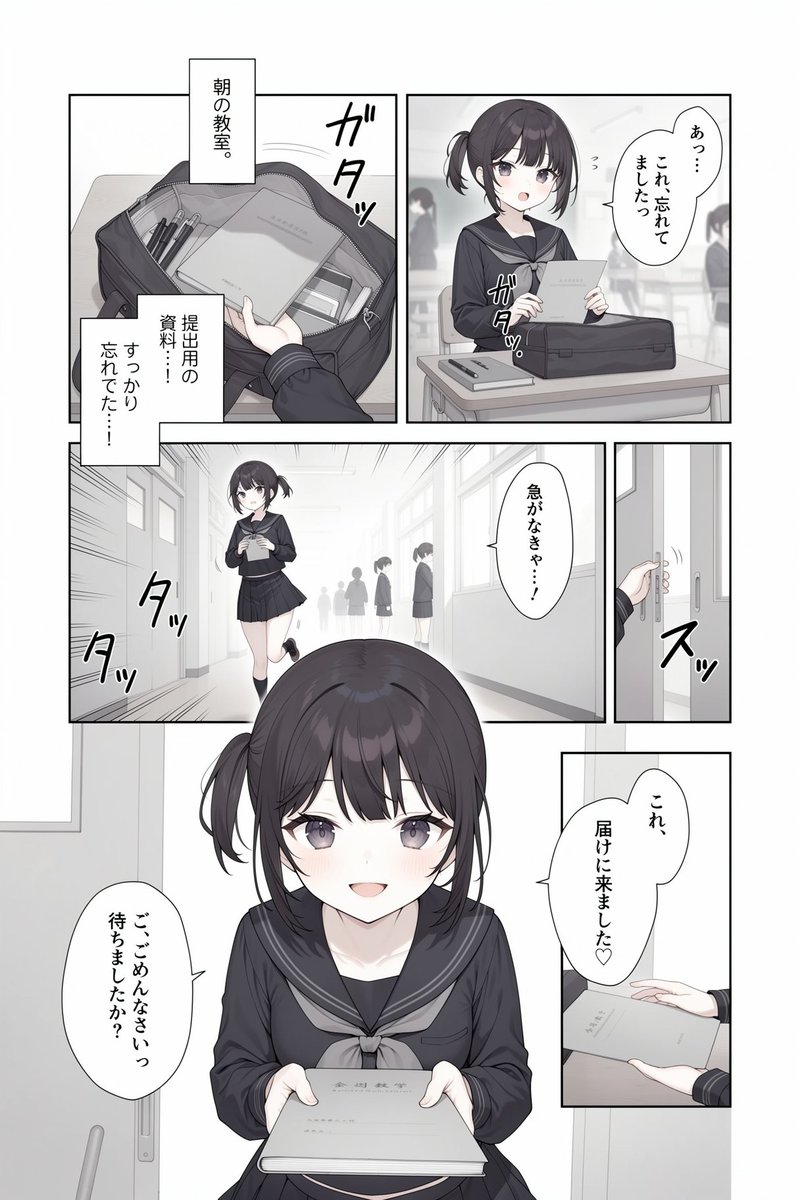
A manga page in Japanese — Kamimoto
Kamimoto (かみもと) uses MOSS-Image with a character LoRA to create a manga page with vertical Japanese text, sound effects and panel layouts.
https://embed.reddit.com/r/StableDiffusion/comments/1xeunzs/my_moss_character_lora_training_results/
u/Any_Tea_3499 shared 17 portraits, the character LoRA training settings and two workflows in r/StableDiffusion.

A poster with a place for everything — IMOLEAYOMIDE
IMOLEAYOMIDE explores text hierarchy and placement in a wireless-earbud poster.
https://www.youtube.com/watch?v=cUeZMUGCxrw
Follow AI Search through local MOSS-Image generation and see how community tools can speed it up.
Kudos to the community creators exploring MOSS and sharing what they make! 👏
See, talk and keep going.
A visitor points a camera at Shanghai landmarks, asks questions and continues the conversation while MOSS-Live retrieves information. Full-duplex interaction lets it listen and speak together. API access is available.
Give a line its rhythm.
Listen to deliberate pauses in generated speech. Use expressive multilingual narration, voice cloning and timing controls for a scene, story or voice-over.
Make motion and sound together.
A car drifts through a rain-soaked neon street, accompanied by engine noise, tire sounds and splashes. MOVA generates video and synchronized audio together from image and text prompts.
Wait for the fall.
In the snowy-street demo, MOSS-VL-Realtime watches a pedestrian cross the frame. It stays silent until the person slips and falls, then raises an alert.
Turn a reference into something real.
Nex-N2.6 turns a single keyboard photo into an animated 3D showcase in Blender. Explore computer use, coding and multi-step creative workflows with the agentic model.
In the Zootopia scene, the model separates the English dialogue by speaker and timestamps each turn. At 0:00, S01 asks “What?” At 0:00.64, S02 starts talking about a friend at the DMV.
Model details:
NEX · MOSS-Image · MOSS-Live · MOSS-Transcribe-Diarize MOSS-TTS · MOSS-VL-Realtime · MOVA